AndrewOgn/colpali-v1.3-merged-onnx-broken
By AndrewOgn · ↓ 0 · ♥ 0 · Updated 2025-01-09
What's in this repo
This page lists the files in AndrewOgn/colpali-v1.3-merged-onnx-broken, including model.onnx.
- 1 ONNX models (.onnx files)
- 12 files, including 6 .json, 2 .safetensors, 1 .md, 1 .onnx, 1 .onnx_data
- Last updated 2025-01-09
ONNX files
| File | Size | Download |
|---|---|---|
| model.onnx | — | Download |
How to use
These ONNX files can be loaded with ONNX Runtime. To inspect a model graph, upload the file to the Netron viewer. Download links point to the original files on Hugging Face.
README
ColPali: Visual Retriever based on PaliGemma-3B with ColBERT strategy
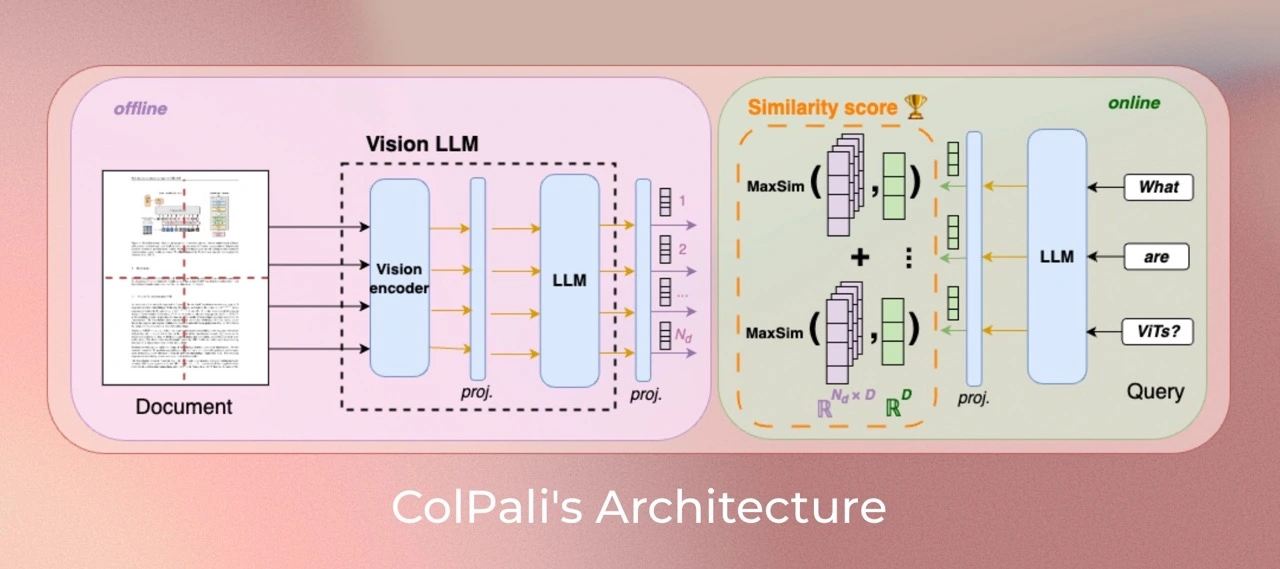
ColPali is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features. It is a PaliGemma-3B extension that generates ColBERT- style multi-vector representations of text and images. It was introduced in the paper ColPali: Efficient Document Retrieval with Vision Language Models and first released in this repository
Model Description
This model is built iteratively starting from an off-the-shelf SigLIP model. We finetuned it to create BiSigLIP and fed the patch-embeddings output by SigLIP to an LLM, PaliGemma-3B to create BiPali.
One benefit of inputting image patch embeddings through a language model is that they are natively mapped to a latent space similar to textual input (query). This enables leveraging the ColBERT strategy to compute interactions between text tokens and image patches, which enables a step-change improvement in performance compared to BiPali.
Version specificity
[!NOTE] This version is similar to
vidore/colpali-v1.3, except that the LoRA adapter was merged into the base model. Thus, loading ColPali from this checkpoint saves you the trouble of merging the pre-trained adapter yourself.This can be useful if you want to train a new adpter from scratch.
Model Training
Dataset
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%). Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both ViDoRe and in the train set to prevent evaluation contamination. A validation set is created with 2% of the samples to tune hyperparameters.
Note: Multilingual data is present in the pretraining corpus of the language model (Gemma-2B) and potentially occurs during PaliGemma-3B's multimodal training.
Parameters
All models are trained for 1 epoch on the train set. Unless specified otherwise, we train models in bfloat16 format, use low-rank adapters (LoRA)
with alpha=32 and r=32 on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a paged_adamw_8bit optimizer.
We train on an 8 GPU setup with data parallelism, a learning rate of 5e-5 with linear decay with 2.5% warmup steps, and a batch size of 32.
Usage
Install colpali-engine:
pip install colpali-engine>=0.3.0,<0.4.0
Then run the following code:
from typing import cast

import torch
from PIL import Image

from colpali_engine.models import ColPali, ColPaliProcessor

model_name = "vidore/colpali-v1.2-merged"

model = ColPali.from_pretrained(
    model_name,
    torch_dtype=torch.bfloat16,
    device_map="cuda:0",  # or "mps" if on Apple Silicon
).eval()
processor = ColPaliProcessor.from_pretrained(model_name)

# Your inputs
images = [
    Image.new("RGB", (32, 32), color="white"),
    Image.new("RGB", (16, 16), color="black"),
]
queries = [
    "Is attention really all you need?",
    "Are Benjamin, Antoine, Merve, and Jo best friends?",
]

# Process the inputs
batch_images = processor.process_images(images).to(model.device)
batch_queries = processor.process_queries(queries).to(model.device)

sess = ort.InferenceSession("AndrewOgn/colpali-v1.3-merged-onnx")
image_embeddings = sess.run([sess.get_outputs()[0].name],{"input_ids":batch_images['input_ids'].numpy(),"pixel_values":batch_images['pixel_values'].numpy(),"attention_mask":batch_images['attention_mask'].numpy()})[0]

pixel_values = np.zeros((batch_queries['input_ids'].shape[0],3,448,448), dtype=np.float32)
# Dummy pixel values
query_embeddings = sess.run([sess.get_outputs()[0].name],{"input_ids":batch_queries['input_ids'].numpy(),"pixel_values":pixel_values,"attention_mask":batch_queries['attention_mask'].numpy()})[0]
query_embeddings = np.array(query_embeddings)
Limitations
- Focus: The model primarily focuses on PDF-type documents and high-ressources languages, potentially limiting its generalization to other document types or less represented languages.
- Support: The model relies on multi-vector retreiving derived from the ColBERT late interaction mechanism, which may require engineering efforts to adapt to widely used vector retrieval frameworks that lack native multi-vector support.
License
ColPali's vision language backbone model (PaliGemma) is under gemma license as specified in its model card.
Because the pre-trained adapter got merged in this model, the license for these weights are also under the gemma license
Contact
- Manuel Faysse: manuel.faysse@illuin.tech
- Hugues Sibille: hugues.sibille@illuin.tech
- Tony Wu: tony.wu@illuin.tech
Citation
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
@misc{faysse2024colpaliefficientdocumentretrieval,
  title={ColPali: Efficient Document Retrieval with Vision Language Models},
  author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
  year={2024},
  eprint={2407.01449},
  archivePrefix={arXiv},
  primaryClass={cs.IR},
  url={https://arxiv.org/abs/2407.01449},
}
Model info
Created: 2025-01-07
Updated: 2025-01-09
View on Hugging FaceFiles (12)
Related models
More from AndrewOgn
More models
No task type declared.