hooman650/bge-large-en-v1.5-onnx-o4
By hooman650 · ↓ 3 · ♥ 0 · Updated 2023-11-22
What's in this repo
This page lists the files in hooman650/bge-large-en-v1.5-onnx-o4, including model.onnx.
- 1 ONNX models (.onnx files)
- 9 files, including 5 .json, 1 .md, 1 .onnx, 1 .txt
- Last updated 2023-11-22
ONNX files
| File | Size | Download |
|---|---|---|
| model.onnx | — | Download |
How to use
These ONNX files can be loaded with ONNX Runtime. To inspect a model graph, upload the file to the Netron viewer. Download links point to the original files on Hugging Face.
README
BGE-Large-En-V1.5-ONNX-O4
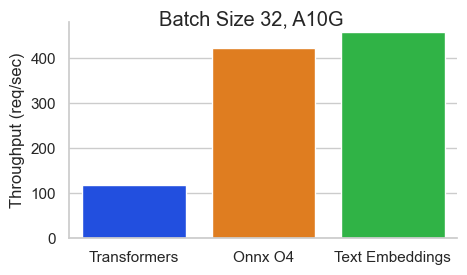
This is an ONNX O4 strategy optimized version of BAAI/bge-large-en-v1.5 optimal for Cuda. It should be much faster than the original
version.
Usage
# pip install "optimum[onnxruntime-gpu]" transformers

from optimum.onnxruntime import ORTModelForFeatureExtraction
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained('hooman650/bge-large-en-v1.5-onnx-o4')
model = ORTModelForFeatureExtraction.from_pretrained('hooman650/bge-large-en-v1.5-onnx-o4')
model.to("cuda")

pairs = ["pandas usually live in the jungles"]
with torch.no_grad():
    inputs = tokenizer(pairs, padding=True, truncation=True, return_tensors='pt', max_length=512)
    sentence_embeddings = model(**inputs)[0][:, 0]

# normalize embeddings
sentence_embeddings = torch.nn.functional.normalize(sentence_embeddings, p=2, dim=1)
Model info
feature-extraction
transformers
transformers
onnx
bert
feature-extraction
en
license:mit
text-embeddings-inference
endpoints_compatible
region:us
↓ 3
♥ 0
Created: 2023-11-21
Updated: 2023-11-22
View on Hugging FaceFiles (9)
.gitattributes
README.md
config.json
model.onnx
ONNX
ort_config.json
special_tokens_map.json
tokenizer.json
tokenizer_config.json
vocab.txt