kashif/music-spectrogram-diffusion
By kashif · ↓ 5 · ♥ 12 · Updated 2023-03-07
What's in this repo
This page lists the files in kashif/music-spectrogram-diffusion, including model.onnx.
- 1 ONNX models (.onnx files)
- 11 files, including 5 .json, 3 .bin, 1 .md, 1 .onnx
- Last updated 2023-03-07
ONNX files
| File | Size | Download |
|---|---|---|
| melgan/model.onnx | — | Download |
How to use
These ONNX files can be loaded with ONNX Runtime. To inspect a model graph, upload the file to the Netron viewer. Download links point to the original files on Hugging Face.
README
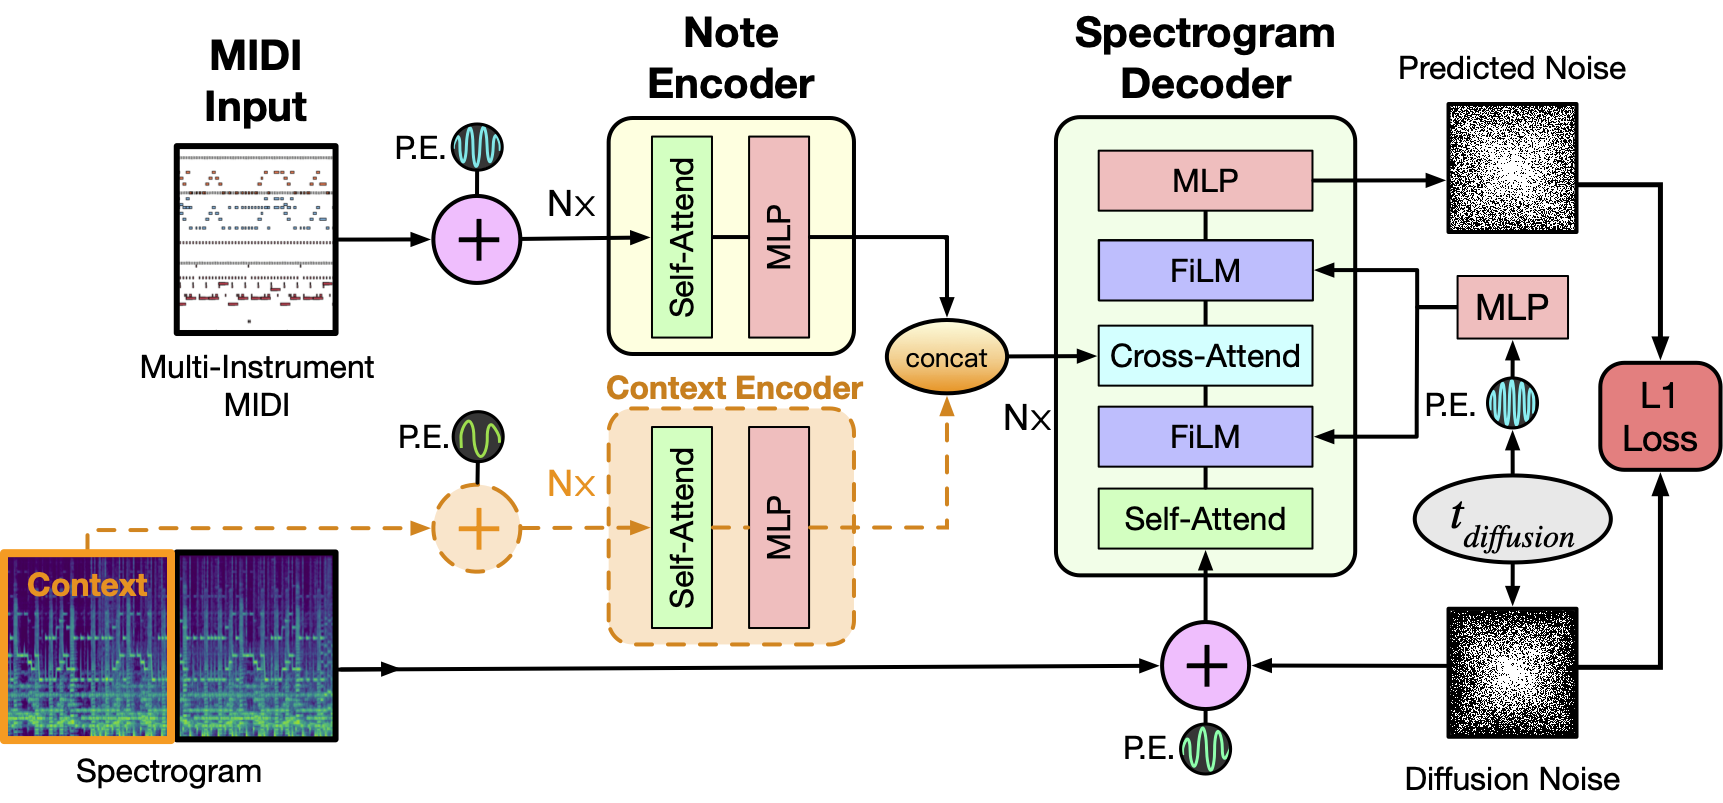
Multi-instrument Music Synthesis with Spectrogram Diffusion
Spectrogram Diffusion by Curtis Hawthorne, Ian Simon, Adam Roberts, Neil Zeghidour, Josh Gardner, Ethan Manilow, and Jesse Engel.
Abstract
An ideal music synthesizer should be both interactive and expressive, generating high-fidelity audio in realtime for arbitrary combinations of instruments and notes. Recent neural synthesizers have exhibited a tradeoff between domain-specific models that offer detailed control of only specific instruments, or raw waveform models that can train on any music but with minimal control and slow generation. In this work, we focus on a middle ground of neural synthesizers that can generate audio from MIDI sequences with arbitrary combinations of instruments in realtime. This enables training on a wide range of transcription datasets with a single model, which in turn offers note-level control of composition and instrumentation across a wide range of instruments. We use a simple two-stage process: MIDI to spectrograms with an encoder-decoder Transformer, then spectrograms to audio with a generative adversarial network (GAN) spectrogram inverter. We compare training the decoder as an autoregressive model and as a Denoising Diffusion Probabilistic Model (DDPM) and find that the DDPM approach is superior both qualitatively and as measured by audio reconstruction and Fréchet distance metrics. Given the interactivity and generality of this approach, we find this to be a promising first step towards interactive and expressive neural synthesis for arbitrary combinations of instruments and notes.
Example usage
from diffusers import SpectrogramDiffusionPipeline

pipe = SpectrogramDiffusionPipeline.from_pretrained("kashif/music-spectrogram-diffusion")
pipe = pipe.to("cuda")

output = pipe("beethoven_hammerklavier_2.mid")

audio = output.audios[0]
Model info
Created: 2022-11-06
Updated: 2023-03-07
View on Hugging FaceFiles (11)
Related models
More from kashif
More models
No task type declared.