kitsunejb/colpali-qdrant
By kitsunejb · ↓ 5 · ♥ 0 · Updated 2025-05-06
What's in this repo
This page lists the files in kitsunejb/colpali-qdrant, including model.onnx, model_fp16.onnx.
- 2 ONNX models (.onnx files)
- 14 files, including 5 .json, 2 .md, 2 .onnx, 2 .onnx_data, 1 .py, 1 .txt
- Last updated 2025-05-06
ONNX files
How to use
These ONNX files can be loaded with ONNX Runtime. To inspect a model graph, upload the file to the Netron viewer. Download links point to the original files on Hugging Face.
README
[!IMPORTANT] This version of ColPali should be loaded with the
transformers 🤗release, not withcolpali-engine. It was converted using theconvert_colpali_weights_to_hf.pyscript from thevidore/colpali-v1.3-mergedcheckpoint.
ColPali: Visual Retriever based on PaliGemma-3B with ColBERT strategy
Please read
conversion/readme.mdfor details about the conversion process and notes. Repo only includes vision models for practical reasons, conversion script supports vision and text as well.
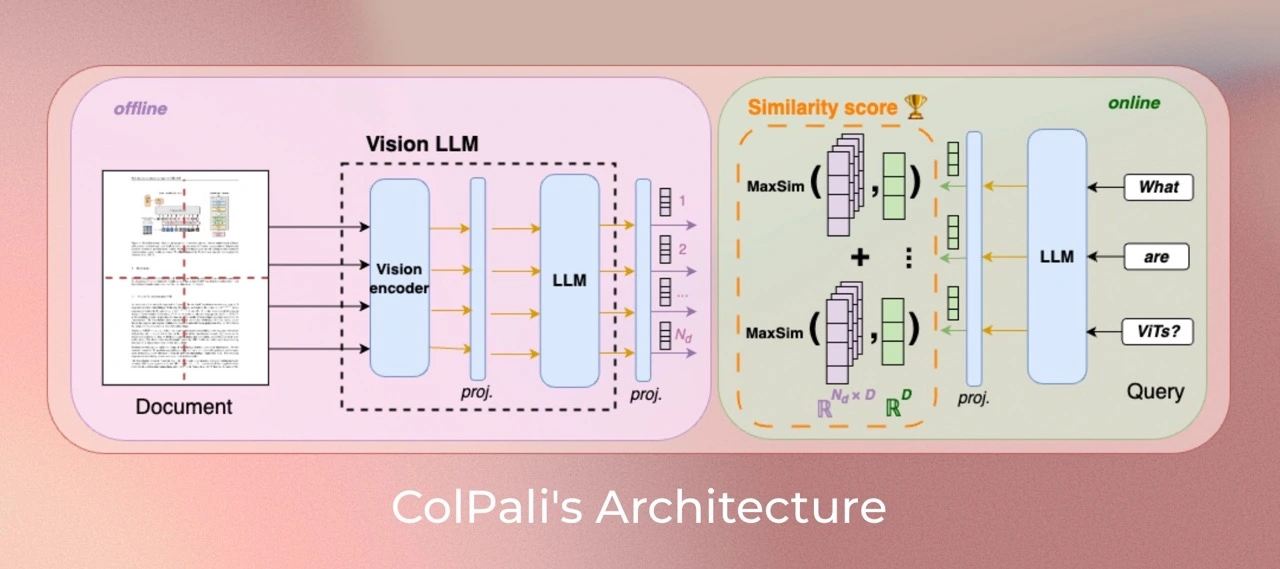
ColPali is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features. It is a PaliGemma-3B extension that generates ColBERT- style multi-vector representations of text and images. It was introduced in the paper ColPali: Efficient Document Retrieval with Vision Language Models and first released in this repository
The HuggingFace transformers 🤗 implementation was contributed by Tony Wu (@tonywu71) and Yoni Gozlan (@yonigozlan).
Model Description
Read the transformers 🤗 model card: https://huggingface.co/docs/transformers/en/model_doc/colpali.
Model Training
Dataset
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%). Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both ViDoRe and in the train set to prevent evaluation contamination. A validation set is created with 2% of the samples to tune hyperparameters.
Note: Multilingual data is present in the pretraining corpus of the language model (Gemma-2B) and potentially occurs during PaliGemma-3B's multimodal training.
Parameters
All models are trained for 1 epoch on the train set. Unless specified otherwise, we train models in bfloat16 format, use low-rank adapters (LoRA)
with alpha=32 and r=32 on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a paged_adamw_8bit optimizer.
We train on an 8 GPU setup with data parallelism, a learning rate of 5e-5 with linear decay with 2.5% warmup steps, and a batch size of 32.
Usage
import torch
from PIL import Image

from transformers import ColPaliForRetrieval, ColPaliProcessor

model_name = "vidore/colpali-v1.3-hf"

model = ColPaliForRetrieval.from_pretrained(
    model_name,
    torch_dtype=torch.bfloat16,
    device_map="cuda:0",  # or "mps" if on Apple Silicon
).eval()

processor = ColPaliProcessor.from_pretrained(model_name)

# Your inputs
images = [
    Image.new("RGB", (32, 32), color="white"),
    Image.new("RGB", (16, 16), color="black"),
]
queries = [
    "What is the organizational structure for our R&D department?",
    "Can you provide a breakdown of last year’s financial performance?",
]

# Process the inputs
batch_images = processor(images=images).to(model.device)
batch_queries = processor(text=queries).to(model.device)

# Forward pass
with torch.no_grad():
    image_embeddings = model(**batch_images)
    query_embeddings = model(**batch_queries)

# Score the queries against the images
scores = processor.score_retrieval(query_embeddings.embeddings, image_embeddings.embeddings)
Resources
- The ColPali arXiv paper can be found here. 📄
- The official blog post detailing ColPali can be found here. 📝
- The original model implementation code for the ColPali model and for the
colpali-enginepackage can be found here. 🌎 - Cookbooks for learning to use the transformers-native version of ColPali, fine-tuning, and similarity maps generation can be found here. 📚
Limitations
- Focus: The model primarily focuses on PDF-type documents and high-ressources languages, potentially limiting its generalization to other document types or less represented languages.
- Support: The model relies on multi-vector retreiving derived from the ColBERT late interaction mechanism, which may require engineering efforts to adapt to widely used vector retrieval frameworks that lack native multi-vector support.
License
ColPali's vision language backbone model (PaliGemma) is under gemma license as specified in its model card. ColPali inherits from this gemma license.
Contact
- Manuel Faysse: manuel.faysse@illuin.tech
- Hugues Sibille: hugues.sibille@illuin.tech
- Tony Wu: tony.wu@illuin.tech
Citation
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
@misc{faysse2024colpaliefficientdocumentretrieval,
  title={ColPali: Efficient Document Retrieval with Vision Language Models},
  author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
  year={2024},
  eprint={2407.01449},
  archivePrefix={arXiv},
  primaryClass={cs.IR},
  url={https://arxiv.org/abs/2407.01449},
}
Model info
Created: 2025-05-04
Updated: 2025-05-06
View on Hugging FaceFiles (14)
Related models
More from kitsunejb
No other models by this author.