返回模型
说明文档
utilityai
本软件包将语言模型能力引入编码环境,提供多种功能,包括:
- 发送消息并提出任何问题
- 聊天和对话
- 讨论函数
- 讨论 numpy 数组
- 讨论 pandas 数据框
- 讨论 pytorch 张量
- 交互式生成函数
- 通过在代码中设置数据来生成函数
- 生成函数并对结果提供注释以进行引导式生成
函数生成功能通过根据预定义的测试用例评估函数,迭代地构建和优化函数。
安装
pip install utilityai
快速入门
安装后下载模型一次
from utilityai.model import download
download()
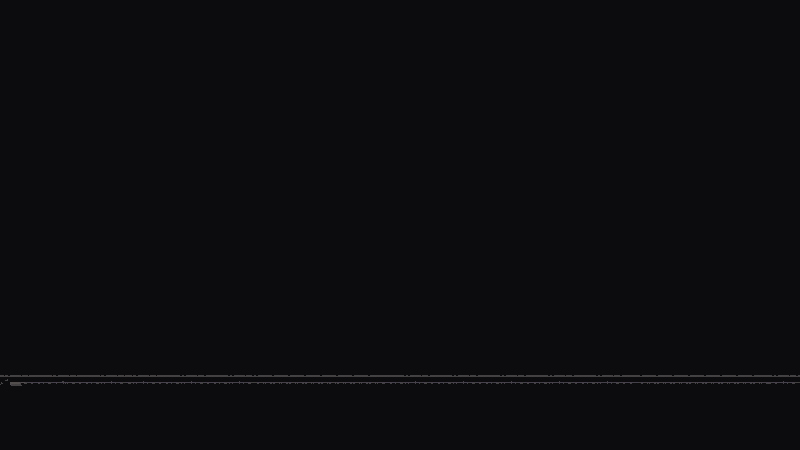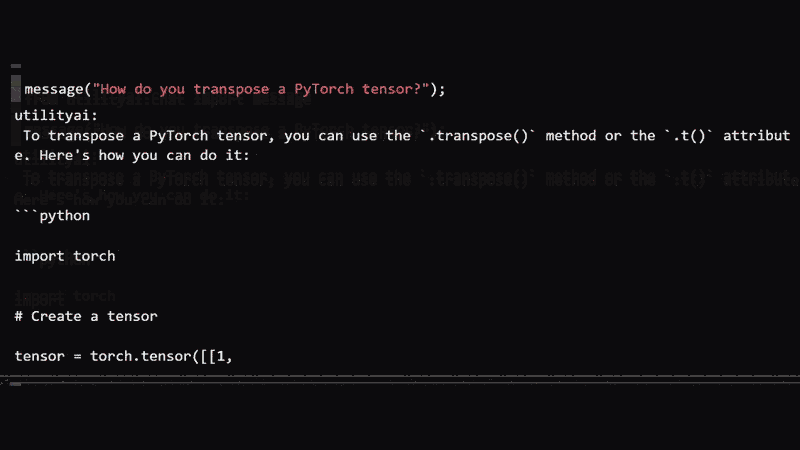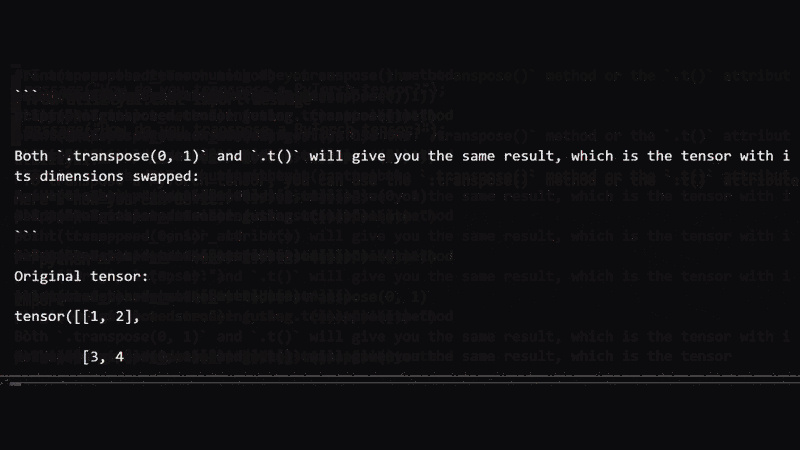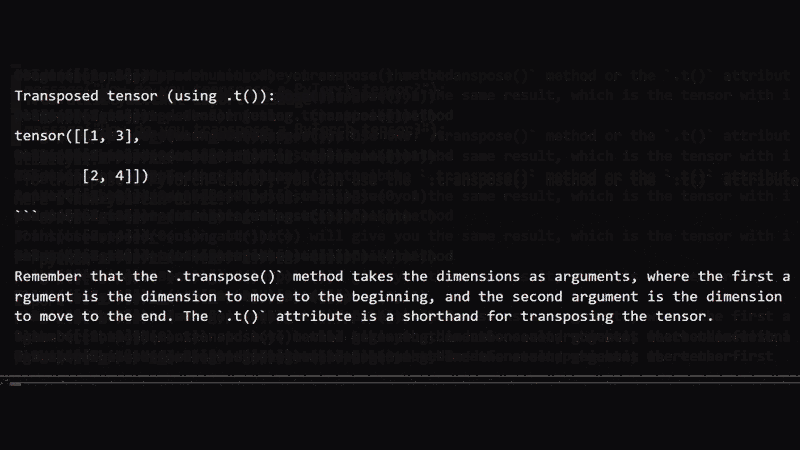
发送消息并提出任何问题
from utilityai.chat import message
message("How do you transpose a PyTorch tensor?");
聊天和对话
from utilityai.chat import message
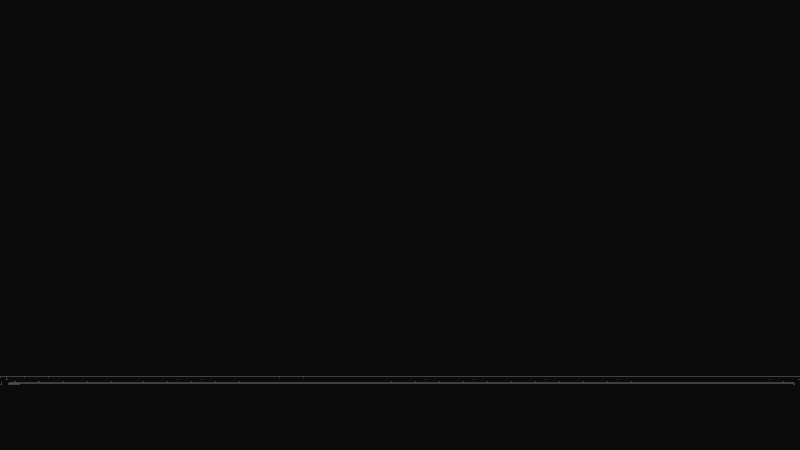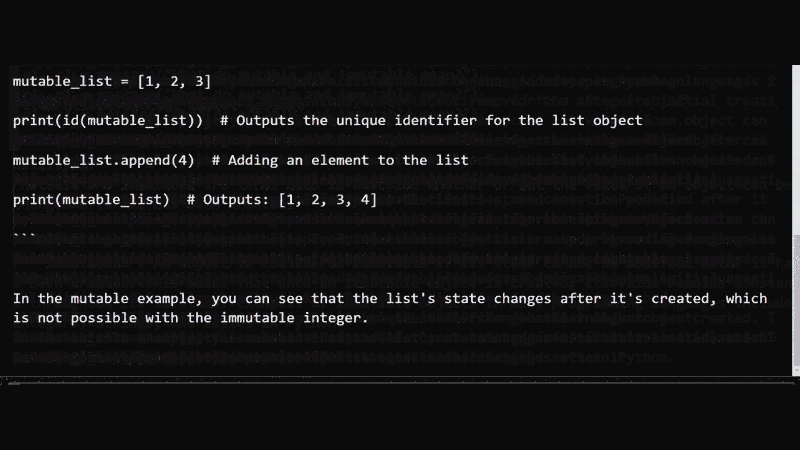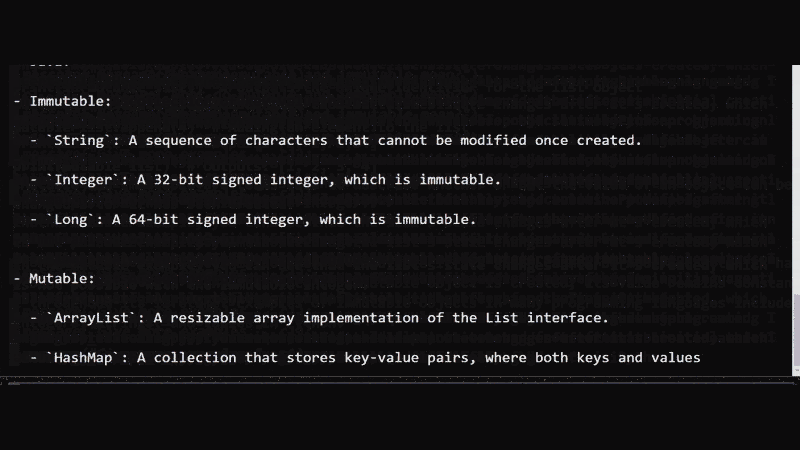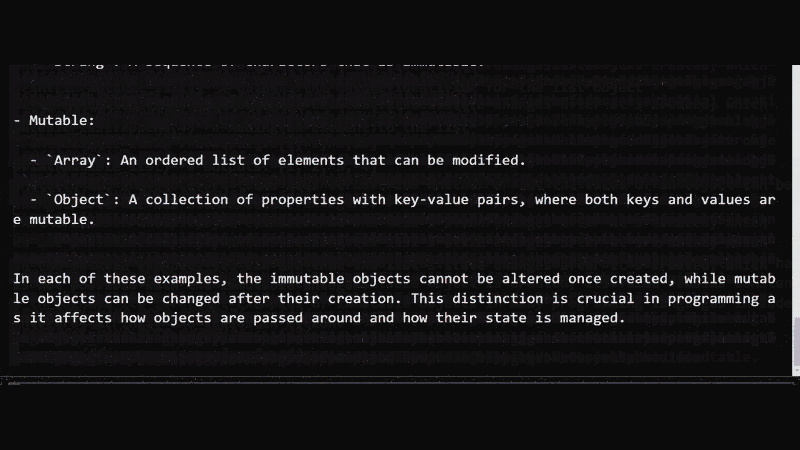
r1, c1 = message("What do mutable and immutable mean?")
message("Give more examples.", c1);
讨论函数
from utilityai.chat import message
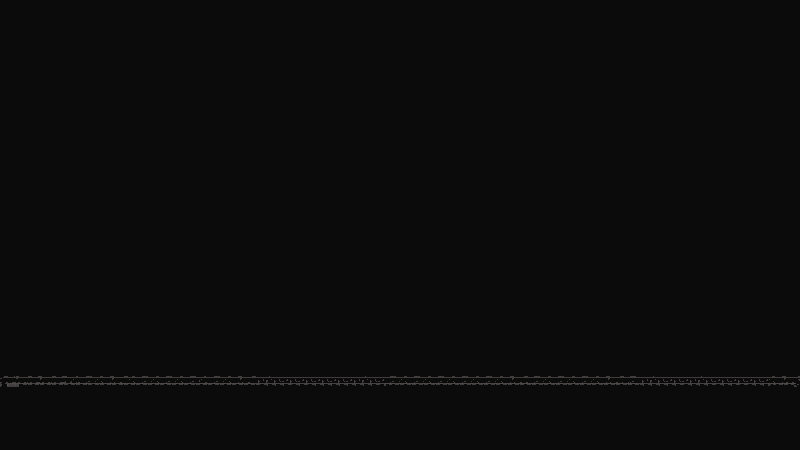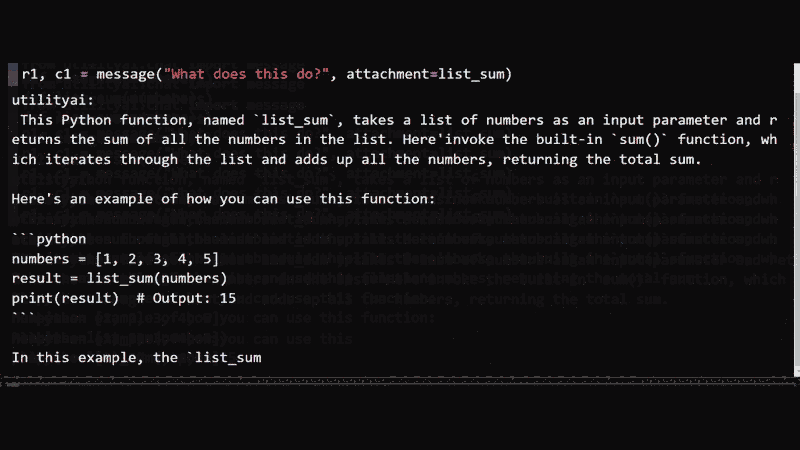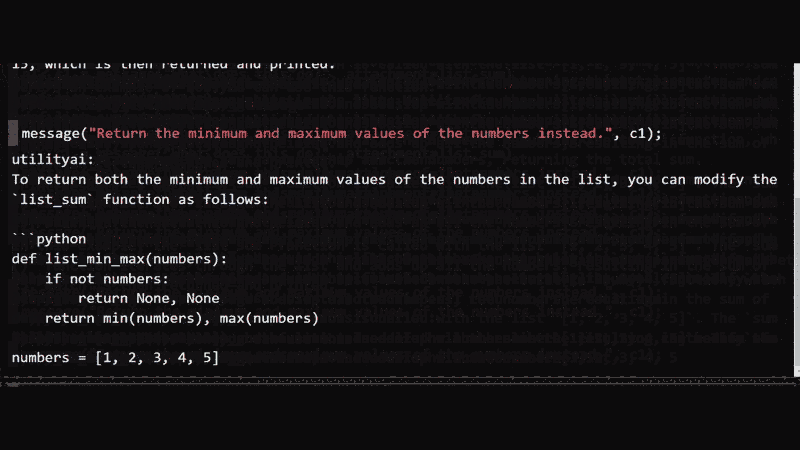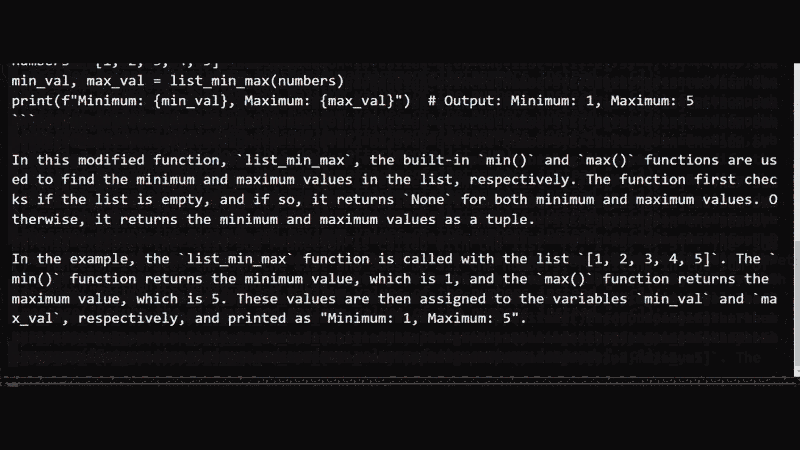
def list_sum(numbers):
    return sum(numbers)
r1, c1 = message("What does this do?", attachment=list_sum)
message("Return the minimum and maximum values of the numbers instead.", c1);
讨论 numpy 数组
from utilityai.chat import message
import numpy as np
array = np.array([[1, 2, 3, 4],
                  [5, 6, 7, 8],
                  [9, 10, 11, 12]])
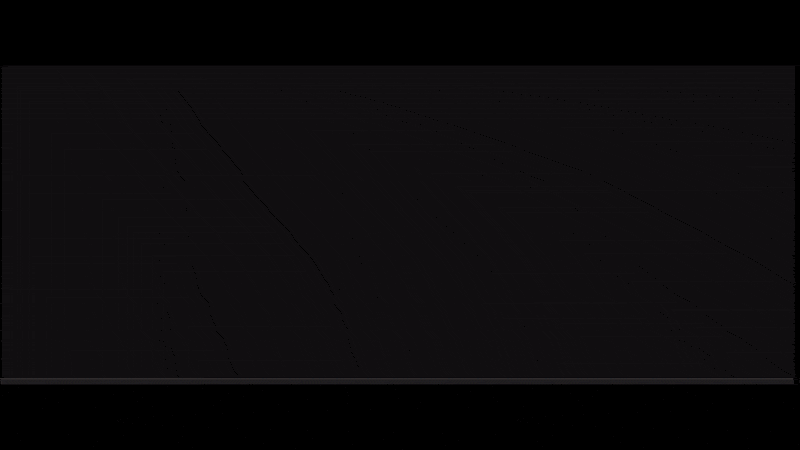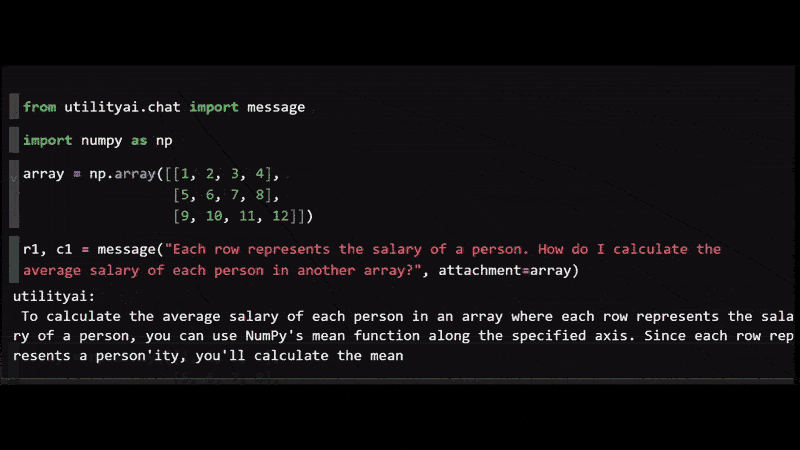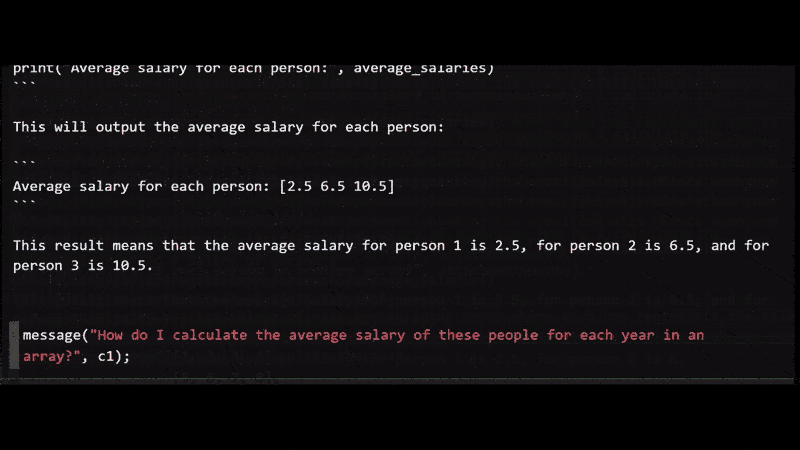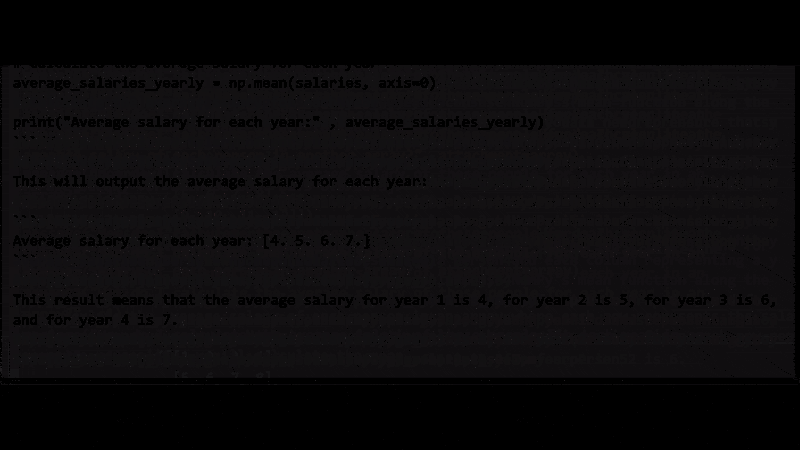
r1, c1 = message("Each row represents the salary of a person. How do I calculate the average salary of each person in another array?", attachment=array)
message("How do I calculate the average salary of these people for each year in an array?", c1);
讨论 pandas 数据框
from utilityai.chat import message
import pandas as pd
data = {
    'Name': ['Alice', 'Bob', 'Charlie', 'David', 'Eve'],
    'Age': [24, 27, 22, 32, 29],
    'Salary': [50000, 54000, 49000, 62000, 58000],
    'Department': ['HR', 'Engineering', 'Marketing', 'Finance', 'Engineering'],
    'Joining Date': pd.to_datetime(['2020-01-15', '2019-06-23', '2021-03-01', '2018-11-15', '2020-08-30'])
}
df = pd.DataFrame(data)
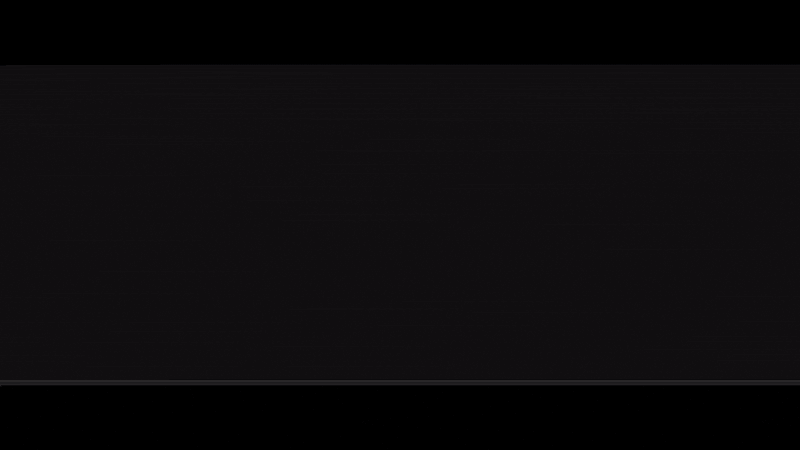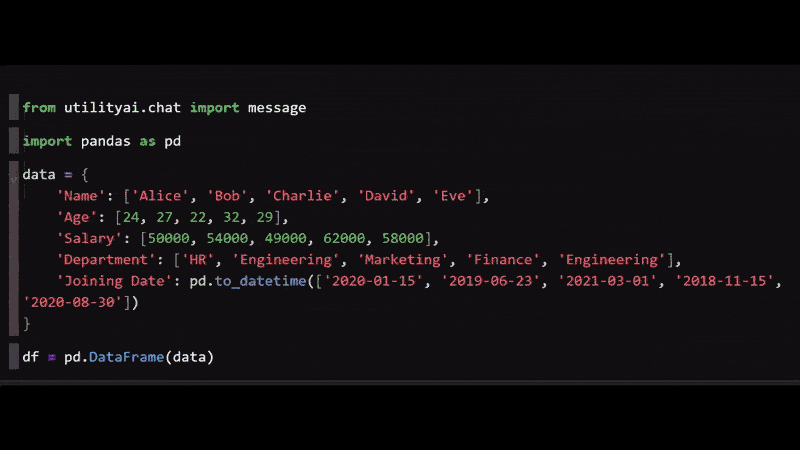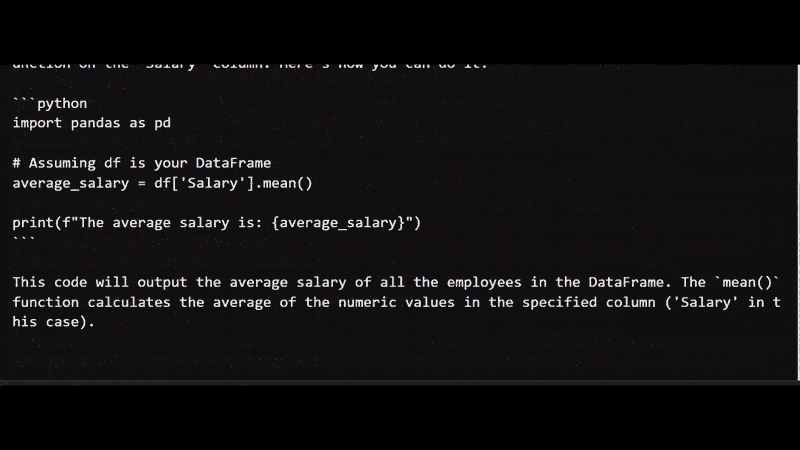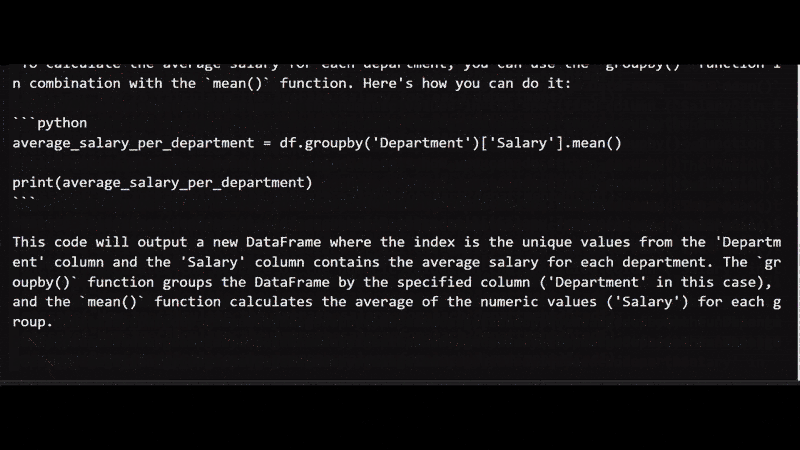
r1, c1 = message("How to calculate the average salary?", attachment=df)
message("How to calculate the average salary for each department?", c1);
讨论 pytorch 张量
from utilityai.chat import message
import torch
tensor = torch.tensor([[1, 2, 3], [4, 5, 6]])
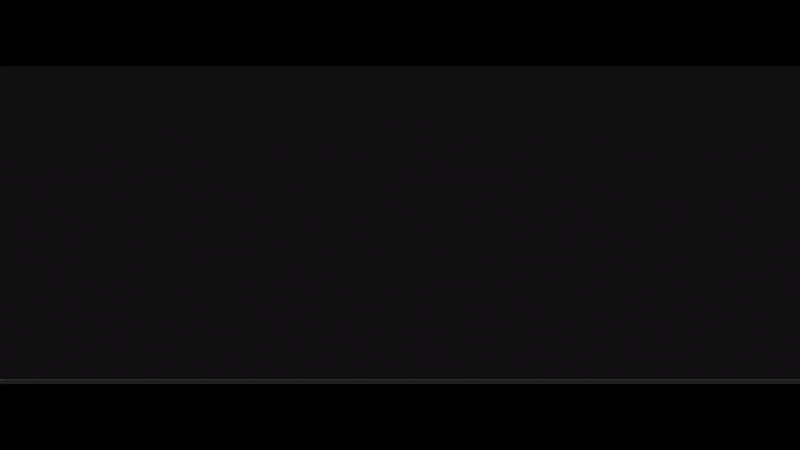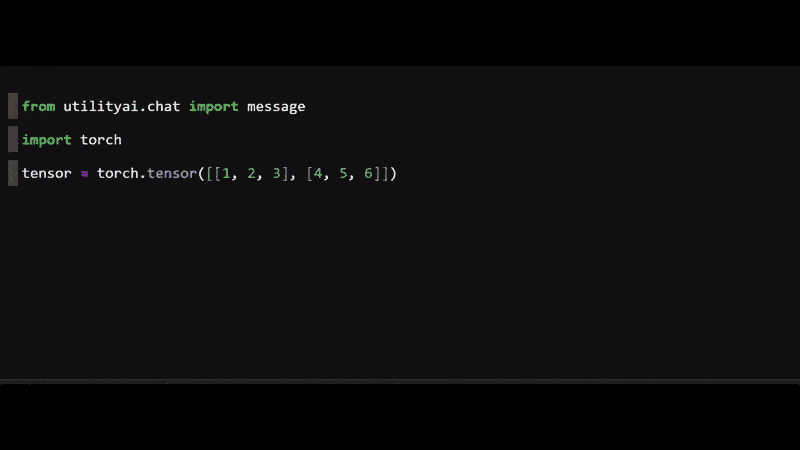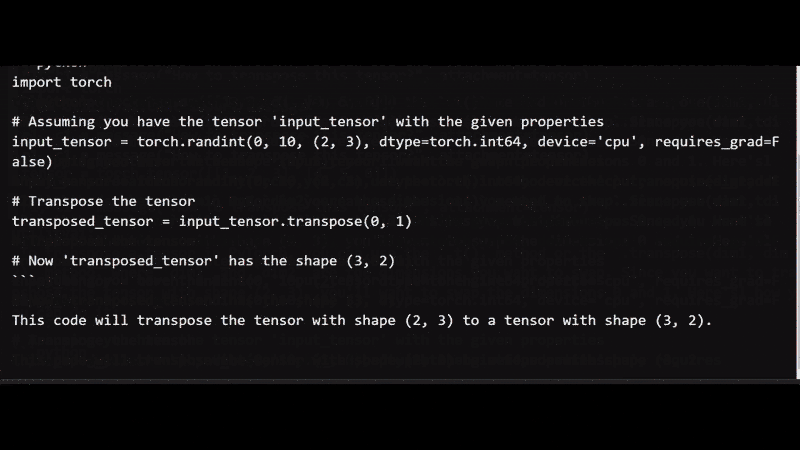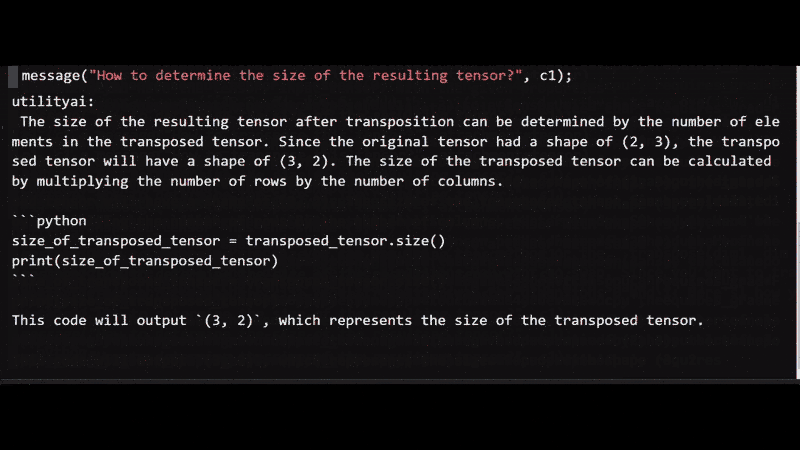
r1, c1 = message("How to transpose this tensor?", attachment=tensor)
message("How to determine the size of the resulting tensor?", c1);
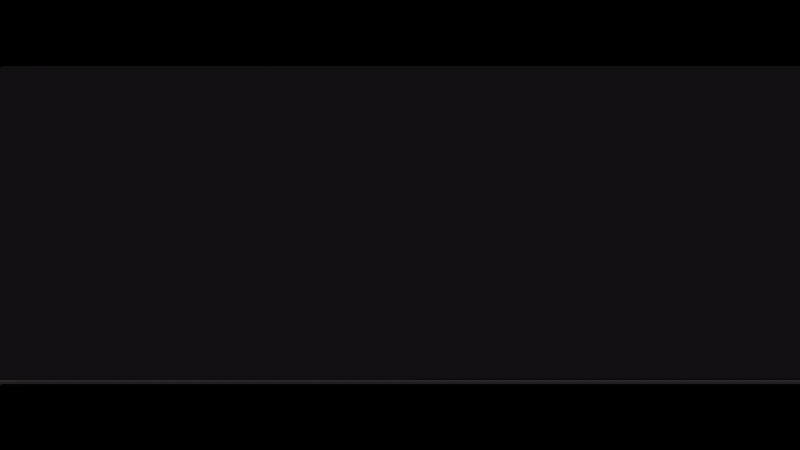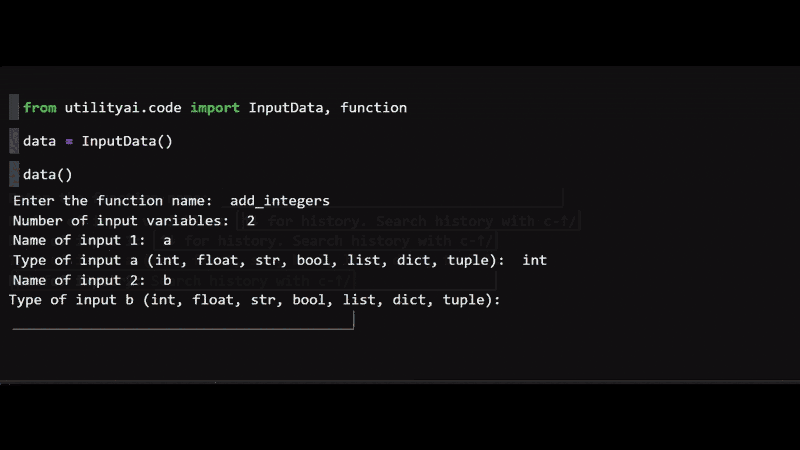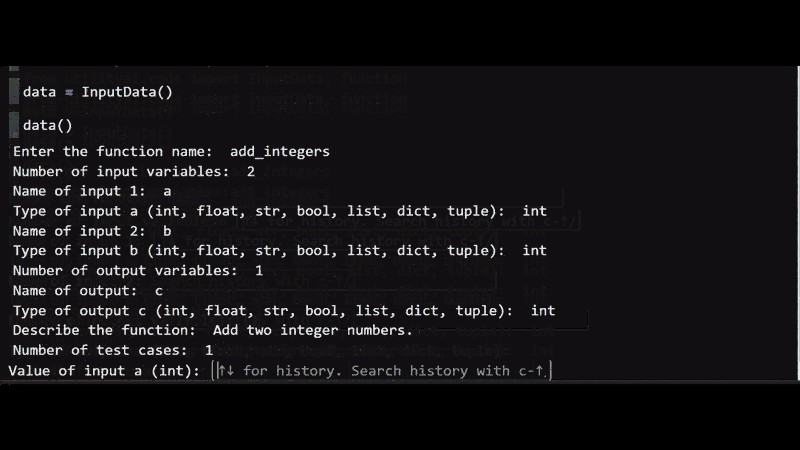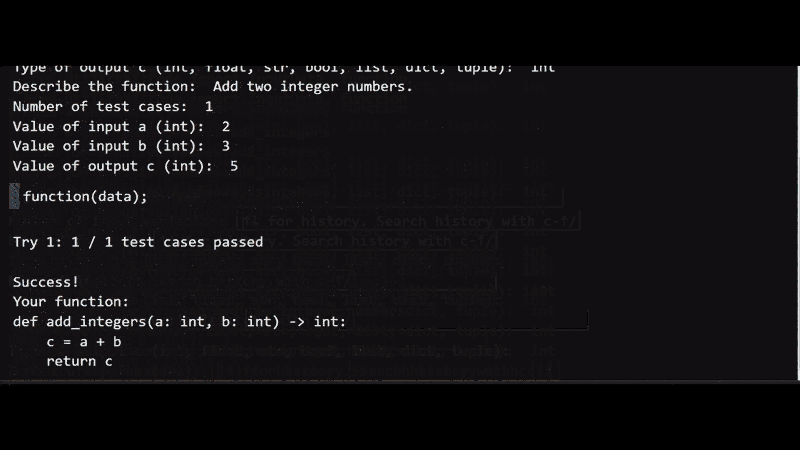
通过先调用 data() 交互式生成函数,然后提供函数信息
from utilityai.code import InputData, function
data = InputData()
data()
function(data);
通过在代码中设置数据来生成函数
from utilityai.code import InputData, function
data = InputData()
data_dict = {
    'function_name': 'prime_number_checker',
    'input_names': ['num'],
    'input_types': ['int'],
    'output_names': ['is_prime'],
    'output_types': ['bool'],
    'description': "A function to check if a given number is prime.",
    'test_cases': [
        {'inputs': [5], 'outputs': [True]},
        {'inputs': [10], 'outputs': [False]},
        {'inputs': [17], 'outputs': [True]}
    ]
}
data.set_data(data_dict['function_name'], data_dict['input_names'], data_dict['output_names'], data_dict['input_types'], data_dict['output_types'], data_dict['description'], data_dict['test_cases'])
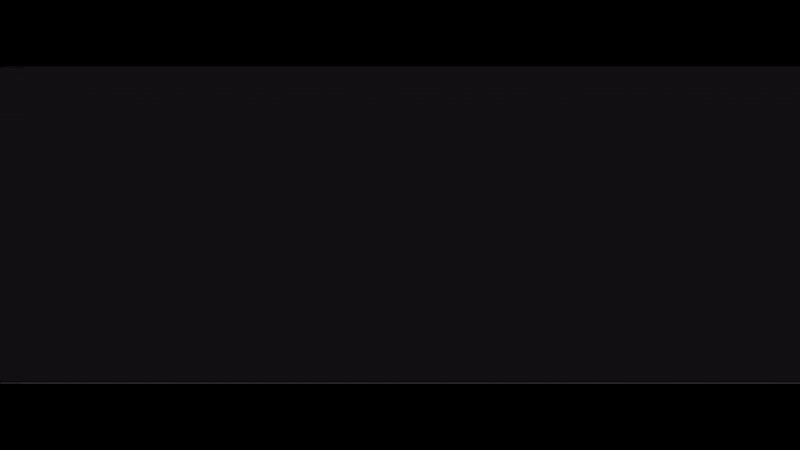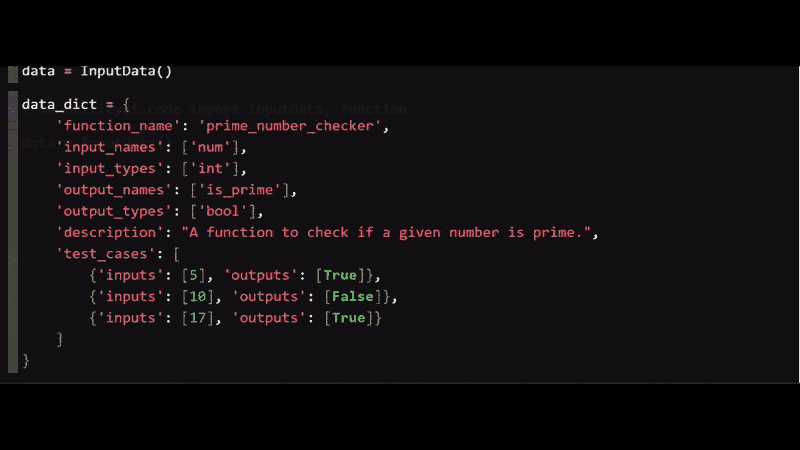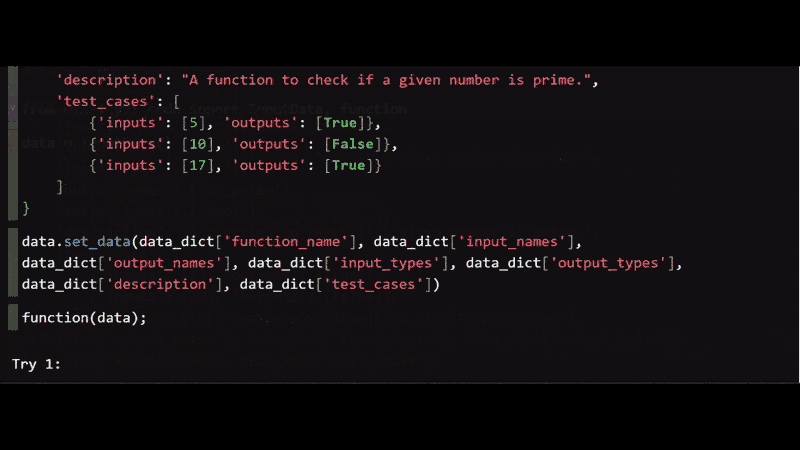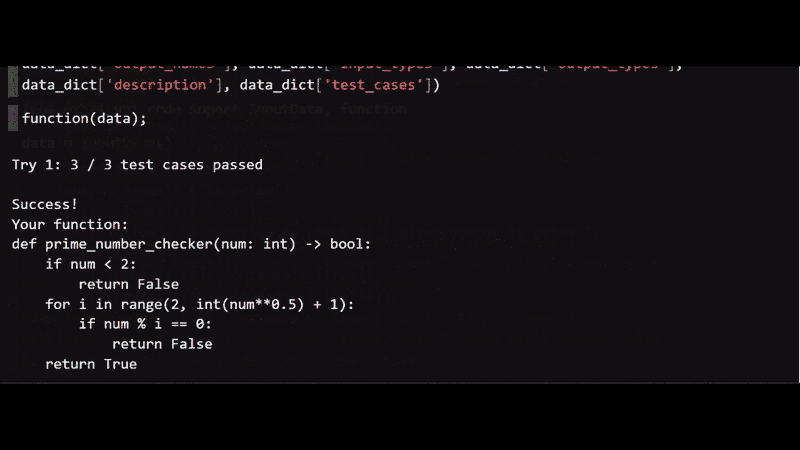
function(data);
生成函数并对结果提供注释以进行引导式生成
from utilityai.code import InputData, function
data = InputData()
data_dict = {
    'function_name': 'vague_function',
    'input_names': ['a', 'b'],
    'input_types': ['int', 'int'],
    'output_names': ['subtract'],
    'output_types': ['int'],
    'description': "A function to subtract two numbers.",
    'test_cases': [
        {'inputs': [1,2], 'outputs': [1]}
    ]
}
data.set_data(data_dict['function_name'], data_dict['input_names'], data_dict['output_names'], data_dict['input_types'], data_dict['output_types'], data_dict['description'], data_dict['test_cases'])
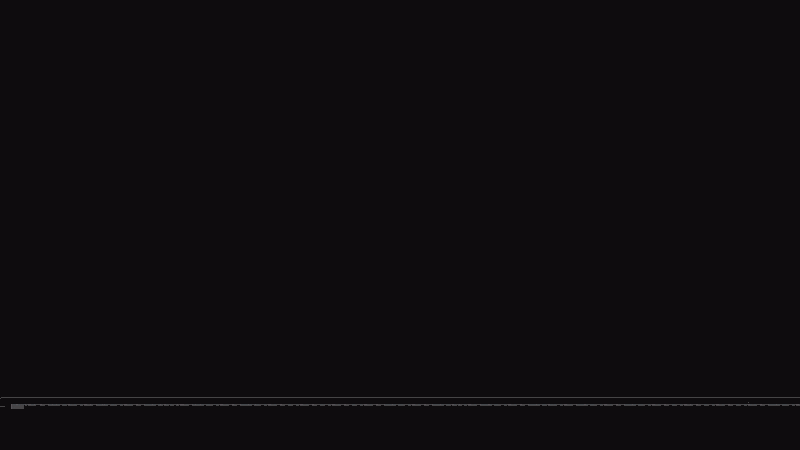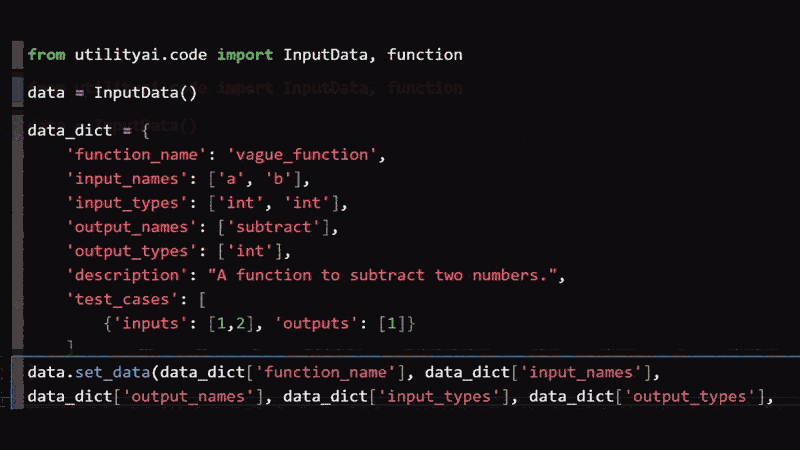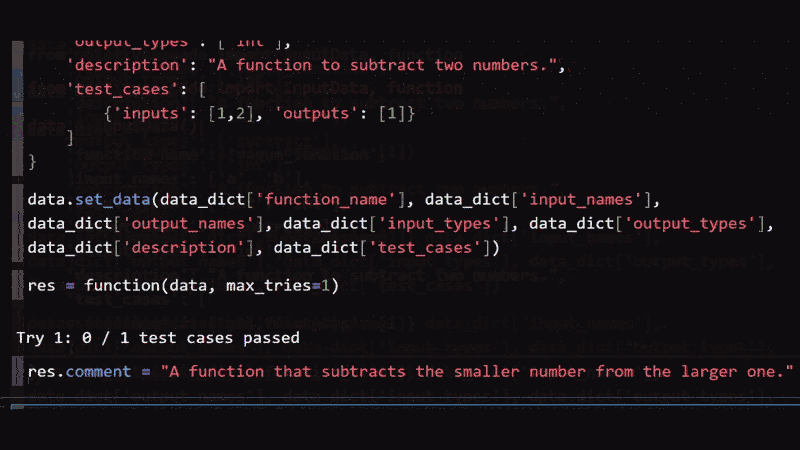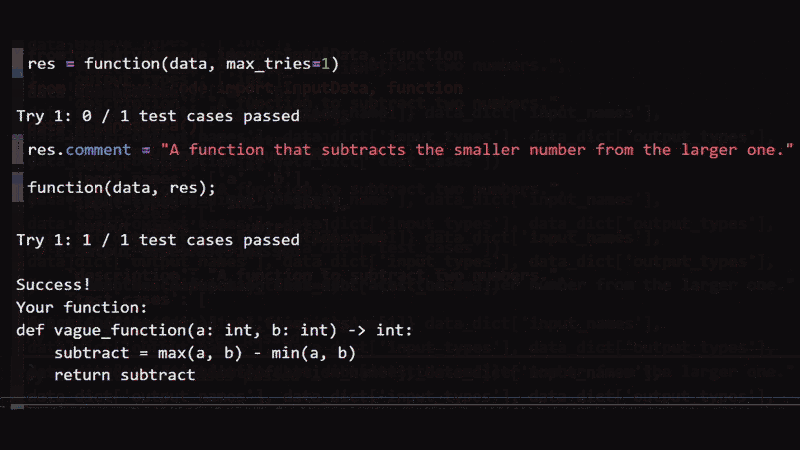
res = function(data, max_tries=1)
res.comment = "A function that subtracts the smaller number from the larger one."
function(data, res);
navid-matinmo/Phi-3-fast
作者 navid-matinmo
transformers
↓ 0
♥ 0
创建时间: 2024-05-28 22:29:08+00:00
更新时间: 2024-06-05 01:05:44+00:00
在 Hugging Face 上查看文件 (11)
.gitattributes
README.md
added_tokens.json
config.json
genai_config.json
navid-matinmo-utilityai-v1.onnx
ONNX
navid-matinmo-utilityai-v1.onnx.data
special_tokens_map.json
tokenizer.json
tokenizer.model
tokenizer_config.json