onnx-community/swin-base-patch4-window7-224-ONNX
By onnx-community · ↓ 12 · ♥ 0 · Updated 2026-03-20
What's in this repo
This page lists the files in onnx-community/swin-base-patch4-window7-224-ONNX, including model.onnx, model_bnb4.onnx, model_fp16.onnx and more.
- 8 ONNX models (.onnx files)
- 13 files, including 8 .onnx, 3 .json, 1 .md
- Last updated 2026-03-20
ONNX files
| File | Size | Download |
|---|---|---|
| onnx/model.onnx | — | Download |
| onnx/model_bnb4.onnx | — | Download |
| onnx/model_fp16.onnx | — | Download |
| onnx/model_int8.onnx | — | Download |
| onnx/model_q4.onnx | — | Download |
| onnx/model_q4f16.onnx | — | Download |
| onnx/model_quantized.onnx | — | Download |
| onnx/model_uint8.onnx | — | Download |
How to use
These ONNX files can be loaded with ONNX Runtime. To inspect a model graph, upload the file to the Netron viewer. Download links point to the original files on Hugging Face.
README
swin-base-patch4-window7-224 (ONNX)
This is an ONNX version of microsoft/swin-base-patch4-window7-224. It was automatically converted and uploaded using this Hugging Face Space.
Usage with Transformers.js
See the pipeline documentation for image-classification: https://huggingface.co/docs/transformers.js/api/pipelines#module_pipelines.ImageClassificationPipeline
Swin Transformer (base-sized model)
Swin Transformer model trained on ImageNet-1k at resolution 224x224. It was introduced in the paper Swin Transformer: Hierarchical Vision Transformer using Shifted Windows by Liu et al. and first released in this repository.
Disclaimer: The team releasing Swin Transformer did not write a model card for this model so this model card has been written by the Hugging Face team.
Model description
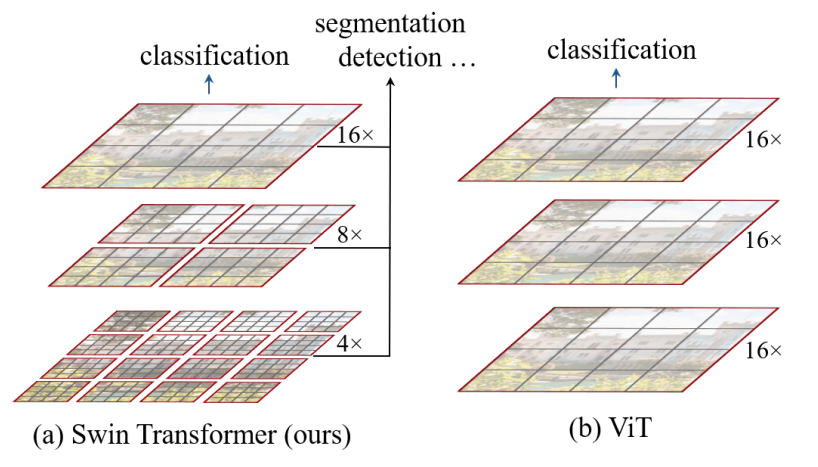
The Swin Transformer is a type of Vision Transformer. It builds hierarchical feature maps by merging image patches (shown in gray) in deeper layers and has linear computation complexity to input image size due to computation of self-attention only within each local window (shown in red). It can thus serve as a general-purpose backbone for both image classification and dense recognition tasks. In contrast, previous vision Transformers produce feature maps of a single low resolution and have quadratic computation complexity to input image size due to computation of self-attention globally.
Intended uses & limitations
You can use the raw model for image classification. See the model hub to look for fine-tuned versions on a task that interests you.
How to use
Here is how to use this model to classify an image of the COCO 2017 dataset into one of the 1,000 ImageNet classes:
from transformers import AutoFeatureExtractor, SwinForImageClassification
from PIL import Image
import requests

url = "http://images.cocodataset.org/val2017/000000039769.jpg"
image = Image.open(requests.get(url, stream=True).raw)

feature_extractor = AutoFeatureExtractor.from_pretrained("microsoft/swin-base-patch4-window7-224")
model = SwinForImageClassification.from_pretrained("microsoft/swin-base-patch4-window7-224")

inputs = feature_extractor(images=image, return_tensors="pt")
outputs = model(**inputs)
logits = outputs.logits
# model predicts one of the 1000 ImageNet classes
predicted_class_idx = logits.argmax(-1).item()
print("Predicted class:", model.config.id2label[predicted_class_idx])
For more code examples, we refer to the documentation.
BibTeX entry and citation info
@article{DBLP:journals/corr/abs-2103-14030,
  author    = {Ze Liu and
               Yutong Lin and
               Yue Cao and
               Han Hu and
               Yixuan Wei and
               Zheng Zhang and
               Stephen Lin and
               Baining Guo},
  title     = {Swin Transformer: Hierarchical Vision Transformer using Shifted Windows},
  journal   = {CoRR},
  volume    = {abs/2103.14030},
  year      = {2021},
  url       = {https://arxiv.org/abs/2103.14030},
  eprinttype = {arXiv},
  eprint    = {2103.14030},
  timestamp = {Thu, 08 Apr 2021 07:53:26 +0200},
  biburl    = {https://dblp.org/rec/journals/corr/abs-2103-14030.bib},
  bibsource = {dblp computer science bibliography, https://dblp.org}
}
Model info
Created: 2026-03-20
Updated: 2026-03-20
View on Hugging Face